Do metrics agree with people?
LLM-based evaluators showed the strongest alignment with human judgments in the study.
Meet ITEM: a closer look at how language AI is evaluated across six Indian languages.
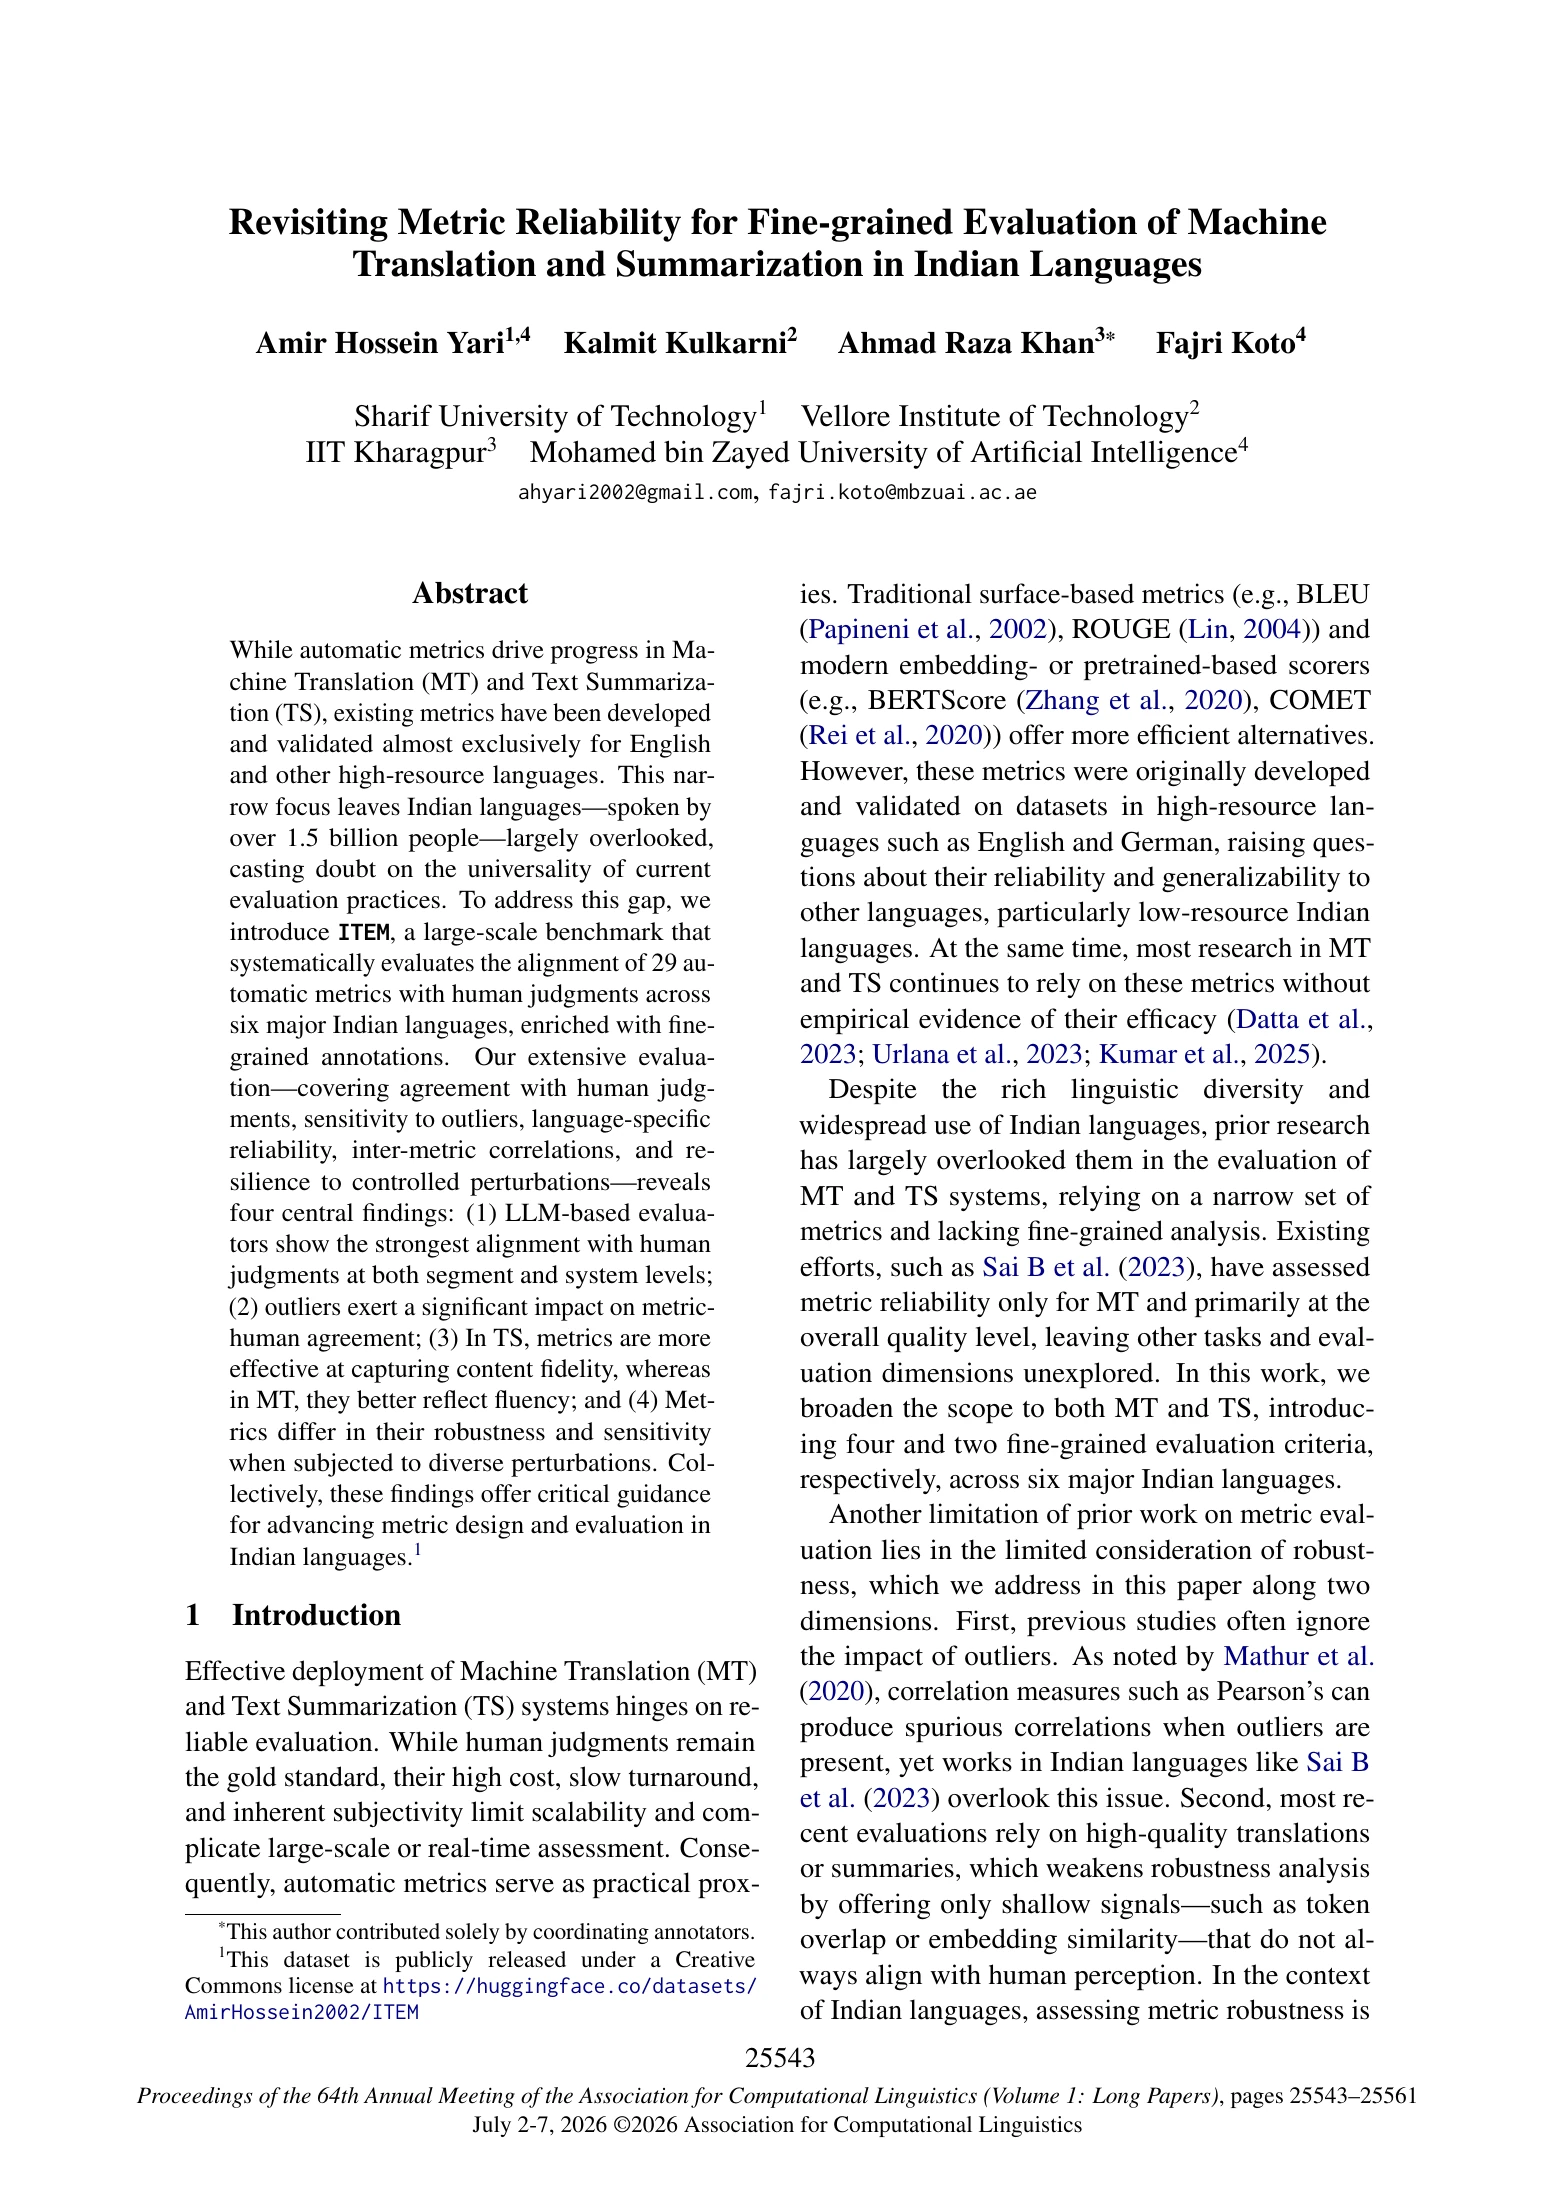
Automatic evaluation is often developed around high-resource languages. Our work examines how well these metrics agree with human judgments for machine translation and summarization in Hindi, Bengali, Marathi, Gujarati, Tamil and Telugu.
My contribution: evaluation pipelines and correlation analysis. The benchmark and findings are the work of our co-author team.
LLM-based evaluators showed the strongest alignment with human judgments in the study.
Outliers affected agreement. Reliability also depended on language, task and the quality dimension being assessed.
Controlled text perturbations revealed differences in metric sensitivity and robustness.
Turn a page. Look closer. Explore the original research.
Loading page…
This page could not be loaded. Try another page, or open the PDF below.
Extracted from the original PDF; equations and tables are best read in the original.
The complete paper is also available through the original PDF link above.
Published July 2026 · ACL, Volume 1: Long Papers
Pages 25543–25561 · DOI: 10.18653/v1/2026.acl-long.1171
Paper source: ACL Anthology. Paper © 2026 Association for Computational Linguistics, distributed under CC BY 4.0. The conference poster was supplied by Kalmit Kulkarni. Page images reproduce the original documents.
Amir Hossein Yari, Kalmit Kulkarni, Ahmad Raza Khan, and Fajri Koto. 2026. Revisiting Metric Reliability for Fine-grained Evaluation of Machine Translation and Summarization in Indian Languages. In Proceedings of the 64th Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers), pages 25543–25561. Association for Computational Linguistics. https://doi.org/10.18653/v1/2026.acl-long.1171